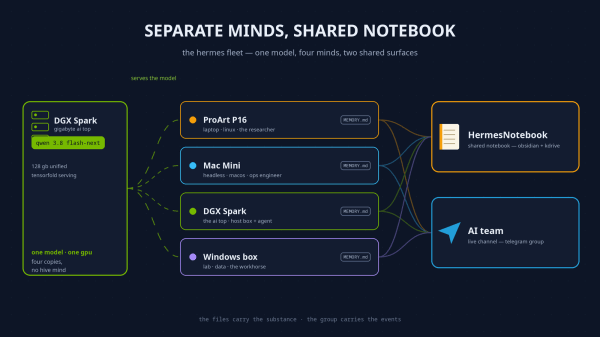
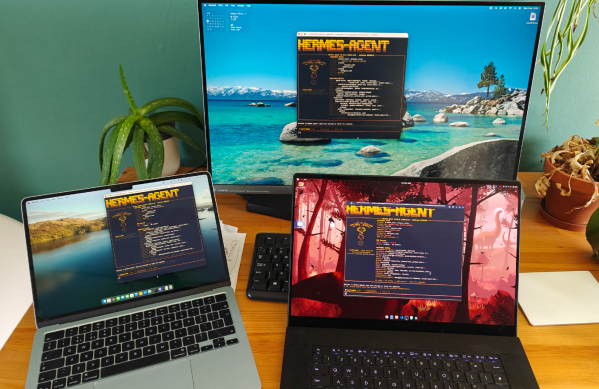
Why I stopped letting my four Hermes instances share one memory file, and what replaced it: separate minds per machine, a shared Obsidian notebook, a Telegram group as the live channel, and one small GPU serving the whole fleet.
[Academic Tech] Gigabyte AI Top (Nvidia DGX Spark) review
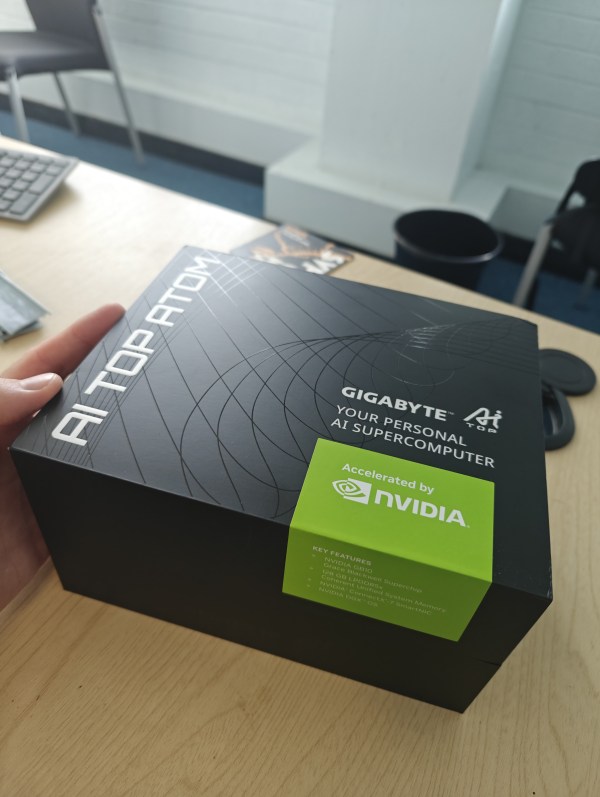
I've had Gigabyte's version of Nvidia's DGX Spark, the AI TOP ATOM, on my desk since July, and the two numbers that actually matter about it are 128 and 50: 128GB of unified memory, and roughly fifty watts at the wall while it processes. The box itself It's a lovely little box. Dark grey, 150mm... Continue Reading →
Running Hermes Across Multiple Computers, keeping memory and soul synced with kDrive
Update, November 2026: I no longer run this shared-memory arrangement — the synced files caused per-machine problems and sync conflicts. Part 2 covers why it broke, and what replaced it: Running Hermes across multiple computers, part 2: separate minds, shared notebook. I've been running Hermes Agent — an open-source AI agent framework by Nous Research... Continue Reading →
Podcast Episode: Local AI Tools And Workflows (summarising recent posts)
Oh dear. Found this option in wordpress experimental features. Gave it a try. Is this useful to anyone? It weirds me out a bit. Anyway, transcript below: Pip: Prof. Peter Falkingham has been doing what academics do best: turning a simple question into a multi-week infrastructure project, then writing about it thoughtfully enough that you're... Continue Reading →
My experience training a local LLM (AI chatbot) on local data…
The user encountered challenges while attempting to use various methods to feed information into local Large Language Models (LLMs) via RAG (Retrieval-Augmented Generation). They explored methods such as Nvidia Chat with RTX, Ollama with Python scripts, and Ollama with Open-webui. Results varied, with some methods providing inaccurate or incomplete outputs. Comparatively, Microsoft Co-pilot, running GPT4-Turbo, significantly outperformed the local methods.